Disaster Recovery Companies – What to Evaluate Beyond SLA Guarantees

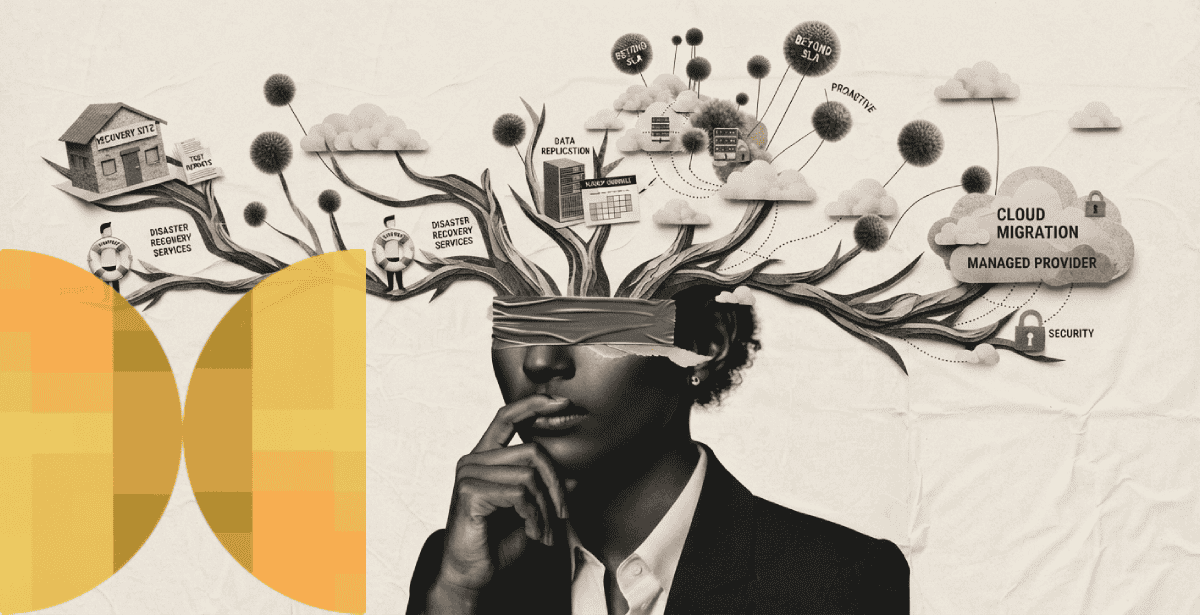
Every vendor pitch from disaster recovery companies leads with the same number. A recovery time objective, backed by an impressive-looking service level agreement.
That number matters, but it’s far from the whole picture. What happens during an actual failure depends on decisions the SLA never mentions.
If you’re hunting for a disaster recovery company, you should know what separates a partner that performs from one that only sounds good on paper. So, read on.
What Should Be Included in Disaster Recovery Services
Disaster recovery services should go beyond backup storage and documented recovery plans. Testing, monitoring, and actual failover execution must be included from day one.
An untested plan is a hypothesis, not a proven capability. Many organizations discover recovery gaps during real incidents, when fixing them becomes far more difficult.
Regular failover drills uncover missing credentials, outdated runbooks, and unclear ownership that paper plans cannot reveal. Quarterly testing should be the minimum for business-critical systems, while frequently updated systems may require monthly drills or testing after major releases.
According to the Federal Emergency Management Agency (FEMA), approximately one in four businesses permanently close following a disaster. This makes recovery testing an operational priority, not an afterthought.
Documentation is equally critical. A runbook understood by only one engineer is not a reliable recovery plan. Version-controlling documentation alongside infrastructure keeps both aligned as systems evolve.
Runbooks must also be clear enough for unfamiliar engineers to follow. Outdated instructions can actively mislead teams during critical incidents.
Ultimately, disaster recovery depends on tested procedures, accurate documentation, and shared knowledge. These investments ensure teams can respond confidently when downtime, pressure, and uncertainty are at their highest.
💡 Recovery planning should account for more than infrastructure failure. A data backup and disaster recovery strategy should consider scenarios such as ransomware, accidental deletion, regional outages, corrupted backups, and third-party service disruptions. Mapping each scenario to recovery procedures, backup frequency, and recovery objectives helps ensure that critical data and systems remain recoverable when unexpected failures occur.
Disaster Recovery Software: The Tooling Layer Behind the Promise
Disaster recovery solutions automate replication, failover orchestration, and recovery validation that would otherwise require manual, error-prone intervention. The right tooling reduces recovery time considerably.
Replication frequency is a core setting worth scrutinizing closely during vendor evaluation, since it directly determines potential data loss. Continuous replication protects far more data than a nightly batch job ever could.
That gap between continuous and batch replication becomes obvious the moment an incident hits mid-afternoon rather than overnight. A nightly-only backup can mean losing most of a full day’s transactions.
Automated failover testing, built into the software itself, catches configuration drift between primary and recovery environments before it matters. Drift between the two environments is one of the most common causes of a failed real recovery.
Vendor lock-in deserves real scrutiny too, since some disaster recovery software works only within a single cloud provider’s ecosystem. That constraint matters considerably for any organization pursuing a genuine multi-cloud strategy.
Evaluating that lock-in risk before committing avoids a painful, costly migration if strategy changes down the line. Portability is worth paying a premium for in most serious disaster recovery evaluations.
How Cloud Based Disaster Recovery Changed the Economics
Cloud based disaster recovery eliminated the need to maintain a fully duplicate, always-on data center sitting mostly idle. Pay-as-you-go recovery infrastructure changed the underlying economics considerably for most organizations.
According to the ITIC 2024 Hourly Cost of Downtime Report, 91% of mid-sized and large enterprises lose upwards of $300,000 for an hour of downtime. That figure makes even a modest recovery infrastructure investment look inexpensive by comparison.
Warm standby and pilot-light architectures both reduce ongoing cost compared to a fully duplicated hot environment running at all times. Choosing between them depends on how quickly recovery genuinely needs to happen.
A warm standby costs more to maintain but recovers faster. A pilot-light approach costs less but takes longer to scale up when the moment finally arrives. That tradeoff should map directly to the actual cost of downtime for each specific system.
Not every system needs the fastest, most expensive recovery tier available on the market. Matching recovery investment to actual business impact avoids overspending on infrastructure protecting a genuinely low-priority workload.
Case Study: Zero Data Loss Journaling Infrastructure for The Miracle Morning
Wellness platform The Miracle Morning needed high-availability infrastructure protecting sensitive user journaling data across a rapidly growing user base. Data loss during any outage was not an acceptable outcome for this application.
DPL built the platform on AWS using Amazon RDS with Multi-AZ deployment specifically for the journaling data layer. The architecture also included CloudFront and automated zero-downtime deployment pipelines.
The results demonstrate what disciplined disaster recovery architecture delivers for a genuinely data-sensitive application. The platform now serves 350,000-plus active members with zero data loss on high-availability journaling data.
The app also maintains a 4.9-star App Store rating across more than 150,000 downloads. That reliability record shows disaster recovery architecture doesn’t have to come at the expense of a smooth user experience.
Understanding Cloud Migration Companies vs Disaster Recovery Companies
Cloud migration companies and disaster recovery companies share overlapping skill sets, but the two engagements demand genuinely different expertise. Migration focuses on moving; recovery focuses on surviving failure once you’ve arrived.
A vendor skilled at migration doesn’t automatically bring the same depth in ongoing failover testing and recovery orchestration. Evaluating both capabilities separately, rather than assuming one implies the other, avoids an unpleasant gap later on.
That gap tends to surface only once, during an actual incident, which is far too late to discover it. Vetting recovery expertise separately from migration expertise during the original evaluation avoids that unpleasant outcome. It’s entirely avoidable for everyone involved in the project.
Asking a prospective vendor directly about their disaster recovery track record surfaces this gap well before a contract gets signed. A confident answer backed by real client references is worth considerably more than polished marketing language alone.
References specific to recovery incidents, not general uptime claims, reveal the most about a vendor’s real-world performance. Any vendor unwilling to share those references is worth treating with real caution.
💡 A vendor’s recovery capabilities should be evaluated against specific scenarios, not just general resilience claims. When evaluating cloud migration companies, also ask how they handle ransomware, regional outages, data corruption, failed backups, and prolonged service disruptions, including the recovery procedures and testing frequency for each. This helps establish whether their disaster recovery expertise can withstand real-world failures rather than just meet documented commitments.
How a Managed Cloud Service Provider Fits in Your Disaster Recovery Plans
A managed cloud service provider handling disaster recovery as part of a broader relationship offers real advantages here. Context about the full environment improves recovery planning considerably, compared to a narrow point solution.
That broader context helps a provider understand dependencies between systems that a narrow disaster recovery vendor might miss entirely. Recovering one system without its dependencies often means recovering something that still doesn’t actually work. It may count as technically restored, but it isn’t functionally usable.
Many organizations have further switched to cloud managed IT services instead of in-house ops. Disaster recovery usually sits alongside monitoring, patching, and cost optimization under one contract.That bundling isn’t just a sales convenience; it genuinely improves recovery outcomes when done well by an experienced, well-resourced provider.
A team already familiar with an environment recovers it faster. A team seeing it for the first time under real pressure struggles considerably more. Mistakes compound quickly in that exact situation, turning a routine failover into a much longer outage.
Cloud managed data center services extend this same logic further. It applies to organizations still running meaningful on-premises infrastructure alongside their cloud workloads today. Not every organization is fully cloud-native yet, and that’s a perfectly normal, common state to be in right now.
Evaluating a managed provider’s disaster recovery capability as part of the broader relationship gives a more complete picture. It’s considerably more realistic overall.
A provider strong on daily operations but weak on incident response is a real, easily overlooked risk. It’s worth naming directly during vendor selection, well before a contract locks the relationship in for years.
That risk rarely shows up in a sales pitch, since incident response is harder to demonstrate than routine uptime metrics.
Choosing a Disaster Recovery Partner That Delivers More Than a Contract
Disaster recovery companies earn trust through demonstrated testing discipline, transparent architecture, and real incident track records, not SLA language alone. The contract matters far less than what actually happens during a real failure.
Asking pointed questions about testing cadence, replication method, and documented incident history separates a serious vendor from one selling reassurance. Those questions should be treated as non-negotiable parts of any real evaluation process.
A vendor who dodges those specific questions, or offers only vague reassurance, deserves real scrutiny before signing anything. Confidence backed by specifics beats confidence backed by polish, every single time. It counts most for the organization actually signing the contract, since they bear the eventual risk.
Moreover, a confident, experienced provider generally welcomes these questions rather than deflecting them. Strong answers work firmly in their own favor too. They build genuine trust faster than any glossy pitch deck ever could on its own, without real substance behind it.
That openness itself is a useful signal worth weighing alongside the actual answers a vendor gives. A provider defensive about scrutiny during a sales conversation is unlikely to be more transparent once under contract.
Vendors who welcome hard questions during evaluation tend to perform noticeably better once trouble actually hits in production. That correlation shows up again and again across many real deployments and evaluations.
And DPL is Ready to Help
With the help of our cloud & DevOps services, your organization benefits from decades of disaster recovery architecture experience. That too ranging from small business to government offices.
Let us know how we can help you via the form below or even the chat window on the right corner. Our team will contact you soon to ensure maximum availability, regardless of disaster.

Topics
Related Articles
-
Hiring App Modernization Services to Effectively Break Monoliths into Microservices
23-Sep-2026 Hazar Hayat
-
How Kubernetes Orchestration Works at Scale — and Why It Matters for Container Management
22-Sep-2026 Hazar Hayat
-
How DevOps Engineering Services Help You Scale Without Full-Time Hiring
21-Sep-2026 Talha Saleem